


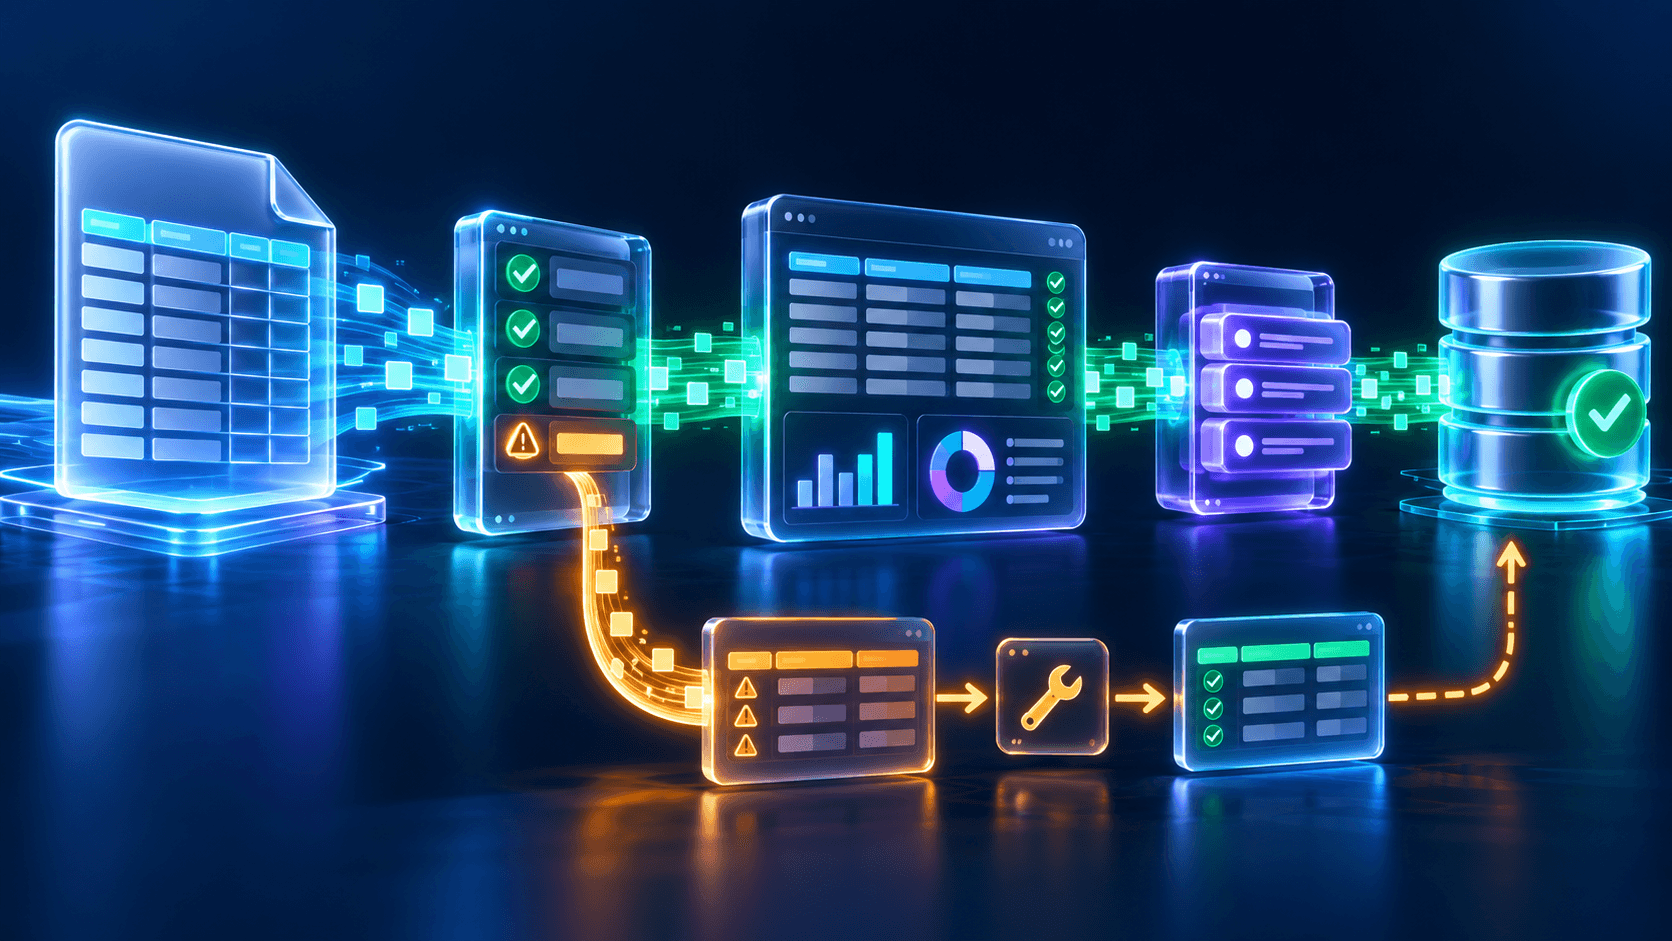
Define the import contract before accepting files
CSV imports let customers move inventory, contacts, invoices, or configuration into a Next.js product quickly. They also concentrate thousands of writes into one action. A reliable importer needs explicit rules for formats, authorization, duplicate handling, preview, partial failure, and recovery before the upload interface is built.
Format
Publish required headers, encoding, delimiter, date rules, field lengths, and a versioned sample.
Meaning
Define whether rows create, update, skip, or reject existing records and which key identifies them.
Outcome
Explain whether the import is atomic or allows partial success, and how users correct failures.
Keep the contract tied to a schema version. A saved mapping should not silently change meaning when the product adds a field or changes a default.
Authorize uploads and put limits around parsing
Resolve the user and tenant on the server, confirm permission to import the target resource, and create an import record before issuing upload access. Store the file privately under a random key scoped to that record. A browser-selected filename, extension, or content type does not establish trust.
For larger files, upload directly to private object storage and let a worker read them. Enforce file bytes, row count, column count, field length, parse time, and per-tenant concurrency. Reject unsupported compression or bound decompression explicitly. Expire abandoned uploads and restrict access to both originals and reports.
Our Next.js upload guide covers the storage and upload flow that can sit beneath this boundary.
Parse records correctly and make column mapping visible
Use a maintained CSV parser that handles quoted delimiters, escaped quotes, embedded line breaks, and the agreed encoding. Splitting lines and commas by hand cannot handle valid quoted records. Retain a logical record number and source location so an error identifies the row the customer can fix.
Normalize headers carefully, reject duplicates after normalization, and show a mapping screen when customers use different column names. Preserve identifiers such as postal codes and account references as strings so leading zeros survive. Treat dates, decimal separators, empty values, and null markers according to the published contract.
Validate the full dataset and stage a reproducible preview
Check field types and ranges, required values, row-level rules, duplicates inside the file, references to existing records, and tenant ownership. Batch reference lookups to avoid one database query per row. A valid sample of the first twenty rows does not prove the rest of the file is valid.
Stage normalized rows with the source checksum, schema version, mapping, duplicate policy, and validation result. Present counts for planned creates, updates, skips, and errors, plus representative examples. Confirmation should reference that immutable staged version; a changed file or mapping requires validation again.
Database state can change between preview and commit. Recheck uniqueness, references, and authorization during processing, and report conflicts according to a documented policy rather than assuming the preview remains current.
Run confirmed imports as bounded background jobs
Long imports should outlive a browser request. Track an operation through uploaded, validating, awaiting confirmation, queued, processing, completed, partially failed, canceled, or failed states. Return a stable import ID and let the interface fetch authorized progress.
uploaded → validating → awaiting_confirmation
         → queued → processing → completed
                      ↘ partially_failed

Each committed batch records:
  import ID, batch ID, source row range,
  created / updated / skipped / rejected counts,
  checkpoint and safe error summary
Use worker leases, bounded concurrency, timeouts, and backpressure. Our background-work guide explains those operating controls.
Make retry behavior part of the write design
Choose a batch size that keeps transactions short and leaves capacity for interactive traffic. Commit the rows and their processing checkpoint atomically so a crash cannot acknowledge work that never committed. Back duplicate rules with database constraints and use a stable import-row operation key when the domain permits it.
For update imports, define which fields may change and whether a version conflict rejects the row or overwrites it. Do not let arbitrary mapped columns become writable properties. Generate domain events through a durable boundary and suppress duplicate notifications when a batch retries.
An all-or-nothing import needs a deliberate transaction or staging-and-activation strategy; committing independent batches is partial success. Do not promise atomicity that the processing model cannot provide.
Give users actionable errors without exposing other records
Report row number, field, safe reason code, and a concise correction hint. Avoid disclosing records in another tenant when a lookup or uniqueness check fails. Cap error samples in the interface while retaining a protected detailed report with its own expiry.
Downloaded CSV error reports may carry untrusted text into spreadsheet software. OWASP documents formula injection and explains why escaping behavior varies between spreadsheet applications. Choose an output policy for the intended viewer and test it there; quoting fields alone does not guarantee formulas remain inert. Preserve a separate machine-readable representation when protective transformations change the original value.
Define cancellation at transaction boundaries
A cancellation request should stop new batches and let the current transaction reach a known outcome. Show how many rows already committed. Retrying rejected rows must create a new validated operation or safely resume the original according to its frozen contract.
Rollback after partial success requires evidence of the changes made. Deleting every record touched by an import is unsafe if some existed beforehand or have since been edited. Store appropriate before-images or operation history when reversal is a product requirement, and reject reversals that conflict with later writes.
Measure progress and exercise failure boundaries
Track validation time, queue age, throughput, transaction duration, duplicate rate, rejected rows, retries, and tenant resource usage. Log import IDs and safe reasons rather than entire customer rows. Retain files only as long as required for the stated workflow.
Test quoted newlines, malformed rows, duplicate headers, Unicode, large fields, leading zeros, ambiguous dates, repeated submissions, permission revocation, worker crashes after commit, concurrent edits, cancellation, and database saturation. Verify that terminal counts reconcile with the parsed row count and that retries produce one intended domain effect.
Next.js CSV import checklist
✓ Formats, duplicate policy, and partial-success rules are explicit
✓ Uploads and every processing step enforce tenant authorization
✓ Parsing has resource bounds and preserves data meaning
✓ Full validation produces an immutable staged preview
✓ Batches commit writes and checkpoints together
✓ Retries and events avoid duplicate effects
✓ Reports are protected and tested for spreadsheet formula risks
✓ Cancellation and reversal explain already committed work
Build a more dependable Next.js application
Endurance Softwares helps teams design, build, test, and operate production-ready Next.js platforms.