


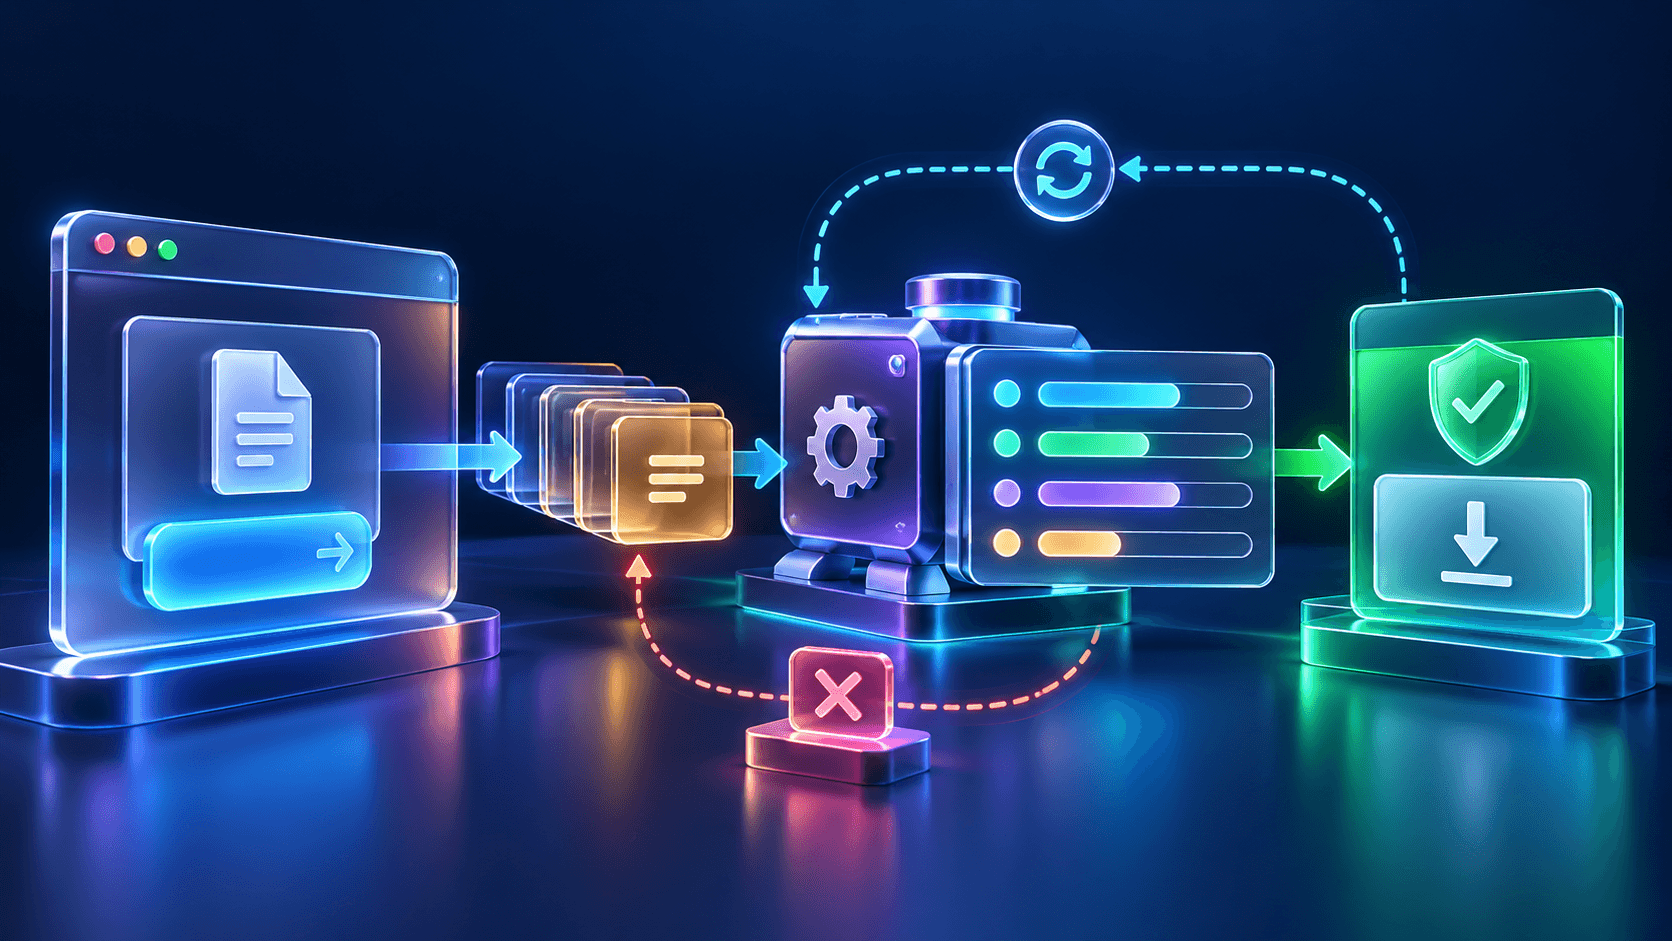
Return an operation after work has been accepted durably
Reports, imports, document generation, and bulk changes can exceed a useful browser request lifetime. A stable operation resource lets the application explain what was accepted, how far it progressed, and where the result lives after a reload or disconnect.
Validate the request and authorization, persist the operation and dispatch intent, then return its identifier and status URL. An HTTP 202 response indicates acceptance rather than completion. Do not acknowledge work that exists only in process memory or a detached promise after the response.
Use an idempotency key for requests whose acknowledgment may be lost. Bind it to tenant, actor, action, and payload so a retry returns the original operation without silently accepting different work.
Expose stable product states rather than worker internals
Define a small state machine with allowed transitions and terminal outcomes. Worker restarts, queue delivery attempts, and provider polling are implementation details; the operation should remain understandable while those change.
accepted → queued → running → succeeded
                    ↘ partially_succeeded
                    ↘ failed
queued / running → cancel_requested → canceled

status: ID, state, revision, timestamps, phase,
completed units, total units when known,
safe error, result reference, retention deadline
Define whether partially succeeded is terminal and which actions support it. Keep result expiry separate from the execution outcome: a successful report can have an expired download without becoming a failed job.
Authorize every status and result request
Use opaque operation IDs, but never treat their unpredictability as access control. Resolve tenant and current identity, then verify permission to inspect the operation and its result. Recheck access after membership changes.
Return safe error codes and user-facing messages without stack traces, provider credentials, internal storage paths, or customer payloads. Define private cache behavior so operation details cannot enter a shared cache. Version the response shape for clients that may remain open during deployments.
Make polling bounded and recoverable
Start with a reasonable polling interval and increase it with jitter when work takes longer or the service reports temporary pressure. Stop at terminal states, pause or reduce work in hidden tabs, and clean up polling when the page unmounts.
Keep the operation ID in a durable navigation path so reloads can resume observation. A temporary network failure should show that status is unavailable while preserving the last confirmed state. Do not turn an unreachable status endpoint into a claim that execution failed.
If a server-provided retry interval is part of the contract, respect it. Bound both client retries and server request cost so thousands of waiting clients do not overload the status store.
Report measurable progress without inventing precision
Expose counts only when the unit and total are meaningful. Processing a thousand rows may be measurable; generating a document with unpredictable layout cost may be better described by phases. An unknown total should remain unknown rather than producing a misleading percentage.
Persist checkpoints at useful intervals instead of writing for every tiny step. Keep progress updates monotonic within their defined phase, and explain when validation discovers additional work. Mark succeeded only after required result storage and verification finish.
Treat streamed updates as hints over durable state
An event stream or WebSocket can reduce polling, but the operation store remains authoritative. Include an operation revision or event sequence so clients can ignore stale updates. On reconnect, retrieve current status before resuming live observation.
Authorize subscriptions, bound connection resources, and close access when permissions change. Avoid sending sensitive result content in progress events. If the stream drops, fall back to the status endpoint without restarting the underlying operation.
Separate requesting cancellation from confirming it
Use an authorized mutation to request cancellation. Persist the request and let workers observe it at safe checkpoints. The response should distinguish cancel_requested from canceled because an in-flight transaction or external action may already be completing.
Define whether partial work remains and how its outcomes are retrieved. Closing a tab or aborting a fetch does not prove the server stopped. Race cancellation against completion atomically so the final outcome reflects committed work rather than whichever UI message arrived first.
The bulk-action guide covers item-level cancellation and partial recovery.
Keep result retrieval and retry policy explicit
Publish a result reference only after it is complete and available. Downloads need current authorization and a defined retention period. Provide an actionable expired-result state, including regeneration when appropriate.
Classify retryable infrastructure failures separately from invalid inputs, permission failures, and conflicts. A user retry may create a linked new operation or resume safe remaining work; explain which behavior applies. Do not automatically repeat completed external effects.
For generated files, see our PDF generation guide.
Test the observer independently from the worker
Lose the acceptance response, reload during execution, disconnect the stream, deliver progress out of order, revoke membership, expire a result, and race cancellation against success. Verify that the client recovers the same operation and never starts duplicate work unintentionally.
Measure queue age, phase duration, stale heartbeat, cancellation latency, terminal-state consistency, and status endpoint load. Use the worker reliability controls in our background-work guide while keeping the public operation contract stable.
Async operation checklist
✓ Acceptance follows durable persistence
✓ Repeated submissions resolve through idempotency
✓ Status and results enforce current authorization
✓ Polling is bounded and survives reconnects
✓ Progress units and phases have clear meanings
✓ Live updates recover from durable state
✓ Cancellation distinguishes request from completion
✓ Result expiry and retry behavior are explicit
Build a more dependable Next.js application
Endurance Softwares helps teams design, build, test, and operate production-ready Next.js platforms.